The Dirty Pages Surprise: When a Read-Only Query Writes Terabytes
For years I had a comfortable explanation for the occasional slow analytical queries on large data with MonetDB:
the data doesn’t fit in memory, the database is doing random I/O on disk (over a memory-mapped file).
It is a reasonable story, and it is often true. But a few days ago I finally looked at the numbers behind that story, and they did not add up.
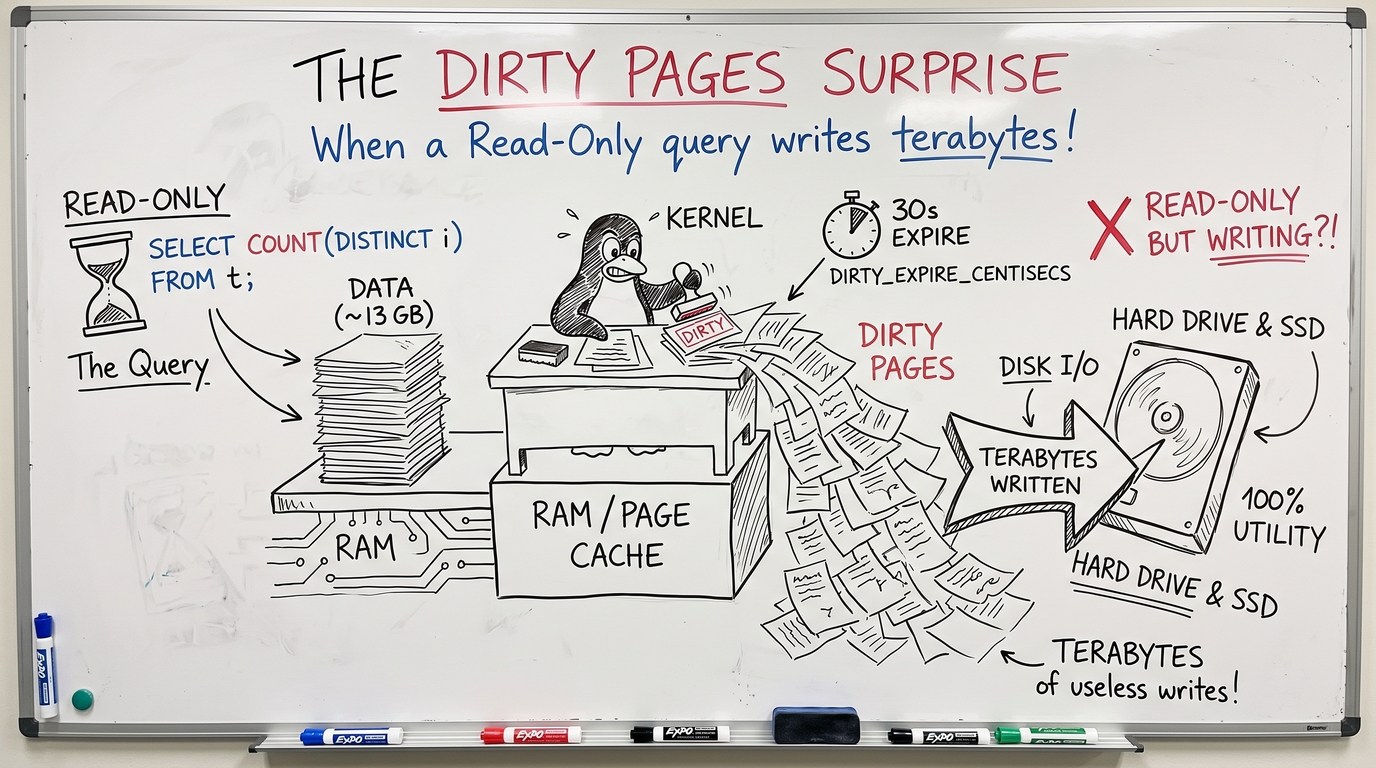
A read-only query was pushing terabytes to disk. That is not random I/O. That is the Linux kernel writing back dirty pages that nobody will ever read.
How MonetDB uses memory
To follow the rest of this, it helps to know one thing about MonetDB’s design.
MonetDB is a column-oriented database built around the idea of a main-memory
database: its performance model assumes the working set lives in RAM. Rather
than managing a buffer pool of its own, it stores each column in a file and
mmaps that file into the process’s address space. Reads and writes then go
through ordinary memory accesses, and it is the kernel’s page cache — not the
database — that decides which pages are actually resident.
A query that should be fast
The setup is deliberately boring. One table, one integer column:
create table t(i bigint);
-- 1,6B rows, 112M distinct values
The query is the kind of thing you run to size a column:
select count(distinct i) from t;
On my desktop (i9-12900T, 64g DDR5 RAM, 980 PRO 2TB disk, kernel 7.2.9-200, MonetDB 56.0) the query took 1 hour 13 minutes. That single number is what made me stop trusting the old explanation and start measuring.
The first look
The obvious first stop is top. The query was using very little CPU — a
single core busy, the rest idle. That already rules out “the algorithm got
slower”. A slow algorithm burns CPU; this one was waiting.
iostat told the rest of the story:
Device   w/s     wkB/s   w_await  %util
nvme0n1  4937    1888716  23.22    100.00
The device was 100% busy writing ~1.9 GB/s. And /proc/pressure/io showed
about 25% full — a quarter of the time, every task on the box was stalled
on I/O.
A read-only count(distinct) query was saturating the disk with writes.
The usual explanation, and why it didn’t fit
My reflex was the old story: the column is ~13 GB, the hash table for the distinct values is large, it doesn’t fit in cache, so we get random I/O. Fine.
But two things did not fit:
- The volume.
/proc/<pid>/ioreportedwrite_bytesin the terabytes over the course of the benchmark. The query only reads the table; the sole thing it writes is its own scratch hash — a few gigabytes at most. Writing that once, or even a handful of times, cannot add up to terabytes of writes. - The memory.
free -hshowed tens of gigabytes ofbuff/cacheand plenty of free RAM. If the working set fit, why was the kernel writing at all?
The second point is the one that had fooled me for years. “Plenty of free RAM” does not mean the kernel will keep your data in RAM. It means the kernel can, if its policy lets it.
Digging in
A backtrace of the running query showed a single thread inside the hash-table build for the distinct count — no surprise, and no smoking gun. The interesting data was in the system counters:
/proc/<pid>/io:write_bytesenormous,read_bytescomparatively small./proc/meminfo:Dirtyaround 5 GB,Writebacksmall — dirty pages accumulating and being flushed continuously.iostat: writes of a few hundred KB each,w_await20–30 ms — the device queue saturated.
Then a scaling test on slices of the table:
| rows | time | ns/row |
|---|---|---|
| 10 M | 0.44 s | ~44 |
| 20 M | 0.92 s | ~46 |
| 100 M | 4.76 s | ~48 |
| 400 M | 35.7 s | ~89 |
| 1.66 B | ~4400 s | ~2660 |
Flat and linear up to 100 M rows, then a cliff. That is not an algorithmic regression; that is a resource boundary. The hash table had grown past the point where the kernel was willing to keep it in RAM.
The realisation
MonetDB does not keep its large temporary structures — hash tables, projections,
intermediate results — in anonymous memory. Once a scratch heap grows past a
threshold (a few gigabytes, and much less when the machine is already busy), it
moves it onto a transient farm: a directory of files that it mmaps. That is
a deliberate, portable design: the operating system’s page cache becomes the
memory manager for scratch data.
The problem is what the kernel does with those pages:
- While a file is open and mapped, its dirty pages belong to a live inode. On reclaim, the kernel must write them back before freeing them — it cannot simply drop them, even though the data will never be read again.
- The kernel flushes dirty pages older than
vm.dirty_expire_centisecs(30 seconds by default) regardless of how much free RAM there is. A query that runs for minutes therefore gets its scratch pages written to disk even on an idle machine. - Writeback is bounded by
vm.dirty_background_ratioandvm.dirty_ratio, which are fractions of RAM (~10% and ~20%). On a 64 GB box that is only ~6 GB and ~12 GB of dirty data before the kernel starts flushing and then throttling the writer.
So the “plenty of free RAM” was mostly clean page cache. The dirty budget for my tens-of-gigabytes working set was a small fraction of RAM, and the 30-second flusher was writing ephemeral data to the device as fast as the query produced it. The query was not doing random I/O. It was being throttled by a writeback policy that had no idea the data was disposable.
The experiment: put the scratch on tmpfs
The quickest way to test the theory is to move the transient farm to a RAM-backed filesystem. In MonetDB this is a per-database property:
mkdir -p /dev/shm/mydb_transient
monetdb stop mydb
monetdb set dbextra=/dev/shm/mydb_transient mydb
monetdb start mydb
The result was unambiguous:
- CPU: 100% the whole time.
- Disk I/O: zero.
- Time: 1 minute 37 seconds.
The same query, the same data, the same binary — from over an hour to under two minutes, purely by changing where the scratch files live.
Why not just use tmpfs everywhere?
Tempting, but it has real drawbacks in a multi-tenant setup:
- Static sizing. A tmpfs has a fixed
size. You must decide up front how much RAM to give it, and that memory is effectively reserved even when idle. - It competes with everything else. Scratch data now consumes RAM directly, alongside the page cache and the database’s own buffers.
- OOM risk. If the working set exceeds the tmpfs and there is no swap, you get an OOM kill instead of a slow query. With swap, you get the disk I/O back, just less predictably.
- Per-project isolation is lost. If each project has its own disk partition, a shared RAM pool is harder to partition fairly than a per-project directory.
In other words, tmpfs is a great diagnostic and a fine choice for some deployments, but it trades a dynamic, on-demand resource (disk) for a static, reserved one (RAM).
The principled fix: tune the kernel, keep the disk
The insight is that the disk-backed transient farm is already a two-tier store: RAM first, disk second. The kernel’s page cache is the first tier. The problem is only that the kernel’s policy flushes the first tier to the second far too eagerly for disposable data.
So keep the transient farm on the project’s disk, and change the writeback policy:
# /etc/sysctl.d/90-monetdb-writeback.conf
vm.dirty_background_bytes    = 17179869184   # 16 GiB: start background flush late
vm.dirty_bytes               = 34359738368   # 32 GiB: tolerate the working set dirty
vm.dirty_expire_centisecs    = 21474836      # ~2.5 days: don't time-out dirty pages
vm.dirty_writeback_centisecs = 60000         # 10 min: flusher rarely wakes
These numbers are specific to one environment. They were chosen for a single NVMe device, 64 GB of RAM, and one database running one I/O-heavy analytical workload at a time. The right values depend on your disk, your RAM, and your concurrency; do not copy them blindly. Be especially careful when several databases — or tenants — share a machine: the dirty budget is a machine-wide resource, and every process competes for the same dirty pool and the same flush capacity. Tune against your own workload, and watch
/proc/meminfo(Dirty,Writeback) and/proc/pressure/iowhile you do.
Why this is safe for persistent data: MonetDB does not rely on the kernel’s
periodic flusher for durability. On commit it fsyncs its write-ahead log, and
recovery replays that log; the kernel’s dirty-expiry timer is not what makes your
database durable, the database is. Relaxing it does not weaken durability.
And why it works for scratch data: with the flusher out of the way, the dirty pages of a transient file stay in RAM for the duration of the query. When the query ends, the transient files are unlinked while still cached, and their dirty pages are then reclaimed without any writeback at all — the inode is orphaned, so there is nothing to write. Only genuine memory pressure pushes them to the project’s disk, which is exactly “RAM first, disk second”.
Choosing values for your environment
The exact numbers matter less than the shape of the change, and the shape follows from two questions.
- How big is the scratch working set? The dirty limits must be large enough
to hold it, or the kernel flushes scratch that is still in use. Size
vm.dirty_bytesandvm.dirty_background_bytesagainst the largest transient working set you expect, not against a fixed fraction of RAM. - How expensive and how predictable is writeback? The faster and more durable the device, the more in-flight dirty data it tolerates. A single spinning disk wants a much smaller budget than an NVMe.
Practical rules:
- Keep
vm.dirty_background_bytesat or belowvm.dirty_bytes, and both well below total RAM, leaving room for the page cache and the database’s buffers. - On a server shared by several databases, give the machine a ceiling you can afford rather than each process its own: the budget and the flush capacity are shared, and over-tuning one process starves the others.
vm.dirty_expire_centisecsandvm.dirty_writeback_centisecsgovern the timer. Raise them only when the scratch is disposable and the database guarantees its own durability — never for a plain file server.- Prefer the
*_bytesknobs over the default*_ratioones: they are independent of RAM, so the limit does not silently change when you add memory. - Whatever you choose, verify it under load. The goal is “RAM first, disk second”, not “never write”.
These settings are safe because MonetDB fsyncs its own log. If other software on the same machine relies on the kernel’s periodic flusher for its durability, relaxing these timers can weaken its guarantees instead.
Results
| Configuration | CPU | Disk I/O | count(distinct i) |
|---|---|---|---|
| Default writeback, transient on disk | ~10% | ~1.9 GB/s writes, 100% util | ~1 h 13 m |
| Transient on tmpfs | 100% | none | ~1 m 37 s |
| Tuned writeback, transient on disk | 100% | negligible | ~1 m 40 s |
The tuned-disk configuration matches tmpfs performance while providing on-demand sizing, no reserved RAM, no OOM risk.
Lessons
- “It’s just random I/O” deserves scrutiny. Measure the volume. A read-only query whose scratch writes run into the terabytes is not doing random I/O; it is being written back by the kernel.
- Free RAM is not the same as usable RAM. The kernel’s dirty-page budget is a fraction of RAM, and its periodic flusher runs on a timer, not on pressure. Your data can be evicted to disk while the machine looks idle.
- The page cache is a two-tier store — but the policy knobs decide which tier
you actually use. The same workload can be RAM-bound or disk-bound depending
on a handful of
sysctlvalues. - Two great pieces of software are not a guarantee of a great combination. The Linux kernel and MonetDB are both excellent. Their defaults, however, were chosen independently, and for large analytical workloads those defaults interact badly. A little tuning — and knowing why — turns an hour into a minute.
The uncomfortable part is how long it took me to look. For years the story “it doesn’t fit in memory” was good enough. It was also wrong.